Multi-Agent RL Under Degraded Communications
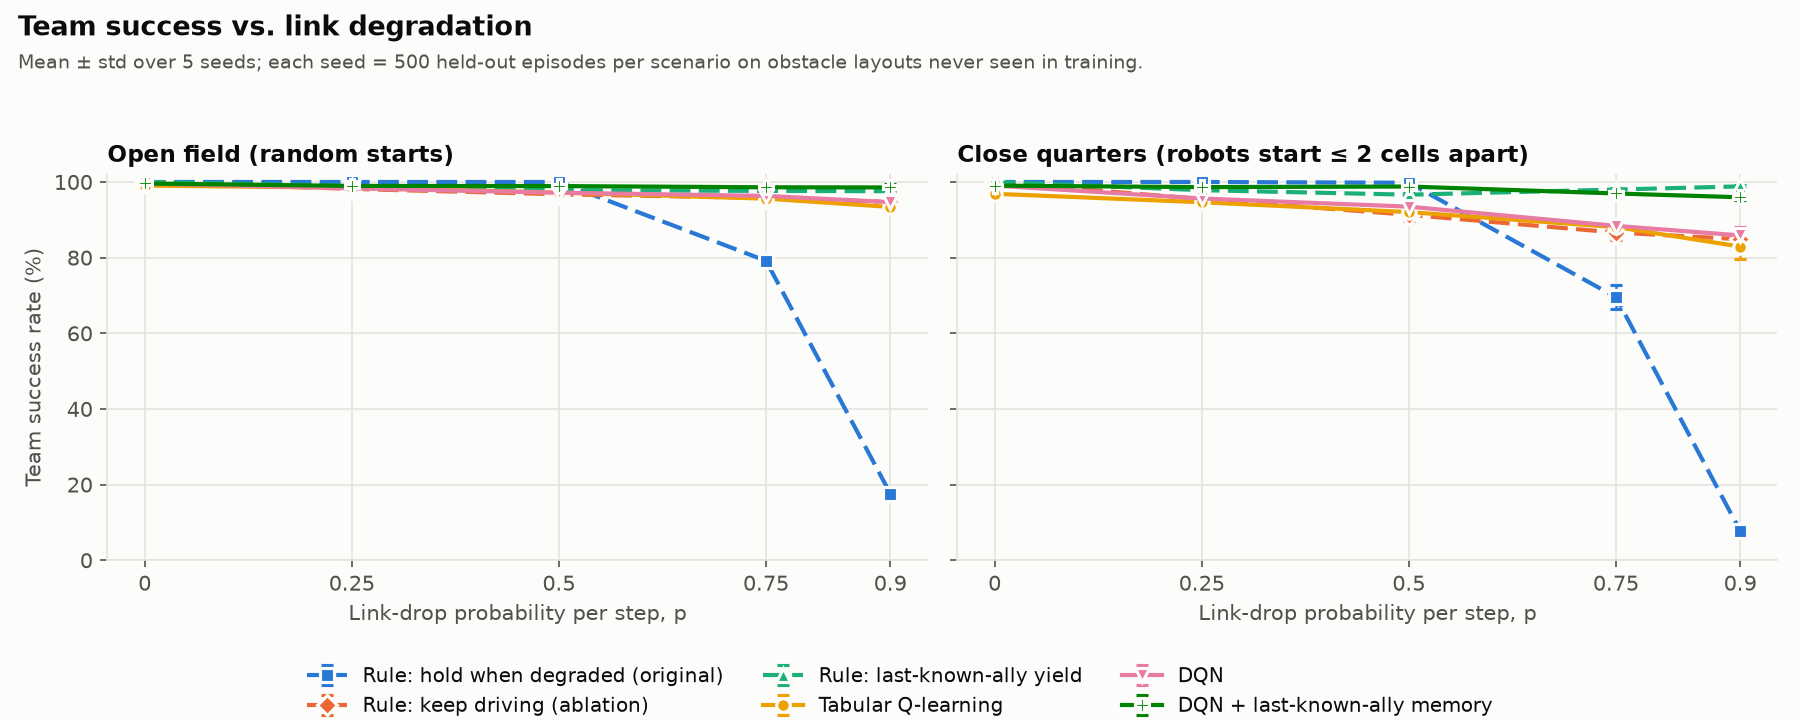
A two-robot gridworld simulator based on my Senior Design project. It compares the original "hold when the link is down" rule with tabular Q-learning and DQN policies on held-out maps.
With the link down 90% of the time, the hold rule finished 17.6% of missions in open field. A DQN that remembers where its partner was last seen finished 98.6% (mean of 5 seeds).
Code, results & write-up →